OpenAI hardens its AI models against distillation
OpenAI is strengthening its models to curb adversarial distillation, a practice that can transfer advanced capabilities to systems with fewer safeguards. Its internal tests reduced the average rate of protected-reasoning extraction from 54.0% to 0.2% in GPT-6.2 Astra.
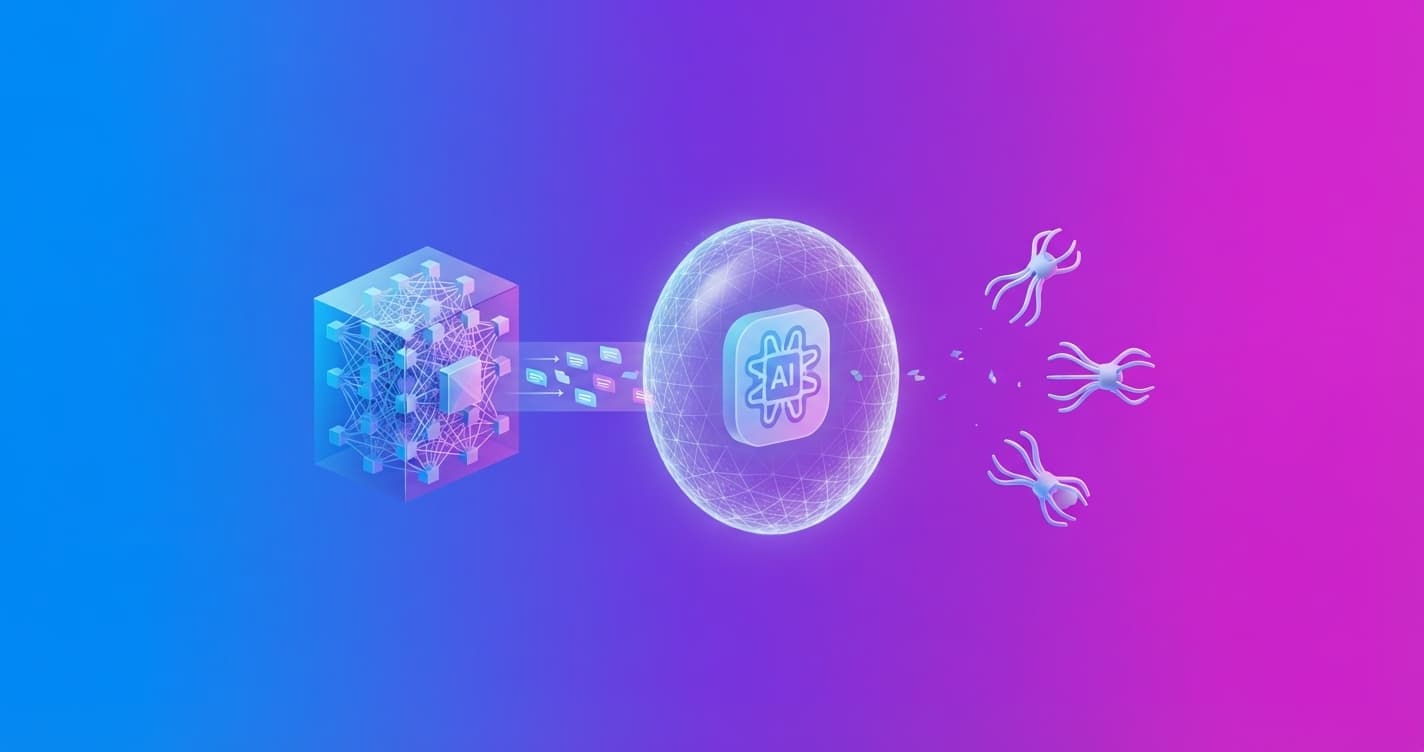
OpenAI is strengthening its AI models to stop other companies or actors from extracting their capabilities and reproducing them without the same safety measures. The company calls this practice adversarial distillation and says it has already detected several campaigns of this kind.
Distillation is a legitimate machine learning technique: a model, known as the teacher, generates responses that are used to train another model, known as the student. The problem arises when someone collects those responses without authorization to create a model with advanced capabilities but without the safeguards that stopped the original model from helping with dangerous tasks.
For example, a model might help a researcher find vulnerabilities in a system. If enough responses are collected and used to train another model, that student could learn to apply similar knowledge for offensive purposes, even if the original model had refused to provide those instructions.
The goal: protecting internal reasoning
OpenAI is focusing much of its defense work on chain-of-thought, the reasoning traces a model generates while preparing a response. Those traces can contain intermediate steps that do not appear in the final answer, making them especially useful for training another system.
The company tested its defenses with automated teams that tried to recover that protected reasoning from previous conversations. In an internal evaluation, the average attack success rate fell from 54.0% in GPT-6 Astra with its original protections to 0.2% in GPT-6.2 Astra with the new measures.
In another adaptive black-box test, where attackers could see only what an external user would see, the success rate remained below 1% for each type of attack in GPT-6.2 Astra. OpenAI says these results come from internal evaluations and that it is still applying some improvements to GPT-6 Astra.
More than blocking a request
The strategy combines several layers. The models are trained to reject attempts to extract their reasoning, while classifiers review both requests and generated responses.
The review also covers arguments sent to external tools. A model could leak protected information not in its visible response, but inside a tool call. Output classifiers can block that content before it reaches the user or another system.
In addition, API protections limit how reasoning can be reused across conversations, users, organizations and model families. In GPT-6.2 Astra and GPT-6.2 Sol, that reasoning is tied to the history of the conversation that produced it. If a previous message is rewritten, the API deletes the reasoning generated after that point.
OpenAI is also looking for coordinated campaigns, not just individual requests. When it identifies a network attempting to extract capabilities systematically, it investigates the related accounts and may take action against thousands or tens of thousands of accounts each week, according to the company. It also shares indicators of compromise with other providers so they can look for similar activity.
What changes for you
If you use these models to code, research or work with tools, the experience should change little. Legitimate requests for explanations and assistance will remain allowed, but attempts to obtain private reasoning or reuse it across models will face more barriers.
The biggest impact concerns models that could copy capabilities in dual-use areas, such as:
- Cybersecurity, where a defensive technique can also be used to attack systems.
- Biology, where knowledge useful for research can facilitate the development of threats.
- Advanced automation, if a model without safeguards receives enough material from a more protected one.
OpenAI says it has identified campaigns linked to the distillation of frontier models and that this issue also has a national security dimension. The company has briefed the U.S. Congress on alleged attempts associated with DeepSeek and Moonshot AI, although those claims are part of its own investigations.
The lesson OpenAI wants the rest of the industry to adopt is clear: protecting reasoning is not enough. Providers need to combine filters on every request with monitoring of entire campaigns, automated tests that try to break the defenses, and coordination between companies.
As advanced models become more accessible, the competition will not be only about who trains the most capable system. It will also be about who can prevent those capabilities from being copied without the limits that make them safe to use.